
1. The Economic Foundations of Bookmaker Margins (The Overround)
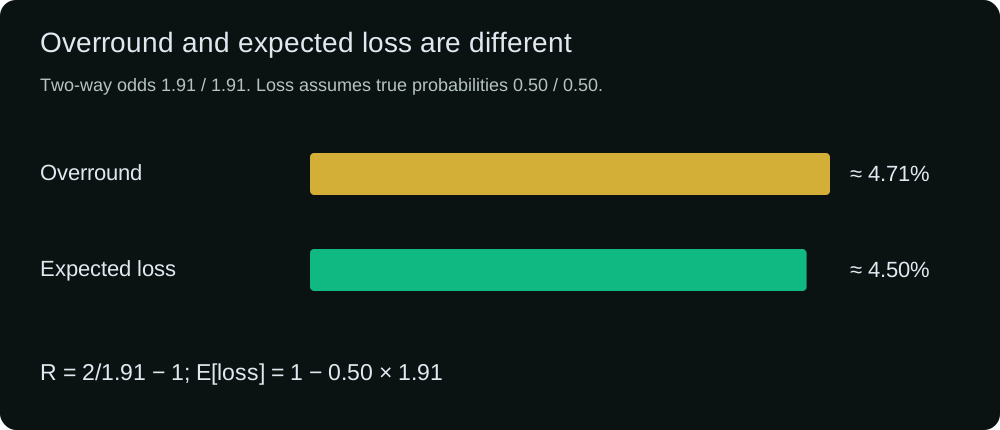
In this illustrative binary market the operator sets both decimal prices to 1.909, below the 2.00 fair price under the assumed 50/50 probabilities. The inverse-price sum then exceeds one. These chosen inputs explain quoted overround; they do not establish universal market prices or risk-free profit for an arbitrary stake distribution.
To conceptualize the overround mathematically, consider an idealized two-sided coin toss where the true probability of landing Heads () or Tails () is perfectly symmetric and objectively known: and . Under zero-margin arbitrage conditions (fair market odds), the decimal odds for each outcome are calculated strictly as the reciprocal of their respective true probabilities:
If two counterparty bettors wager $100 each on opposite sides of this fair market, the sportsbook collects $200 in total turnover ($100 + $100) and disburses precisely $200 () to the winning bettor. The operator's net risk-free revenue is exactly zero (). This represents a zero-sum game devoid of commercial viability for a commercial gaming enterprise.
The reciprocal quote 1/1.909 is the break-even probability, approximately 52.38345%, whereas the example assumes 50% for each true outcome. Those are different quantities. The excess of the reciprocal-price sum is a property of the quote vector; the expected return additionally uses the assumed p. Matching liabilities gives the state-independent book result described next.
For a complete mutually exclusive market, genuine probabilities sum to one. In the symmetric example, equal accepted stakes also equalize liabilities because the two odds are equal. With odds 1.909 and 100 units on each side, total receipts are 200, payout 190.9 and gross net revenue 9.1, a4.55% hold before costs. The quoted overround is instead . This balanced construction does not describe every real book.
2. The Mathematical Inevitability of Long-Term Loss under the Overround
Positive quoted overround describes prices. To infer an expected loss for a particular selection, a probability model is also needed. The proportion of bettors who lose is an empirical question and cannot be deduced from the overround formula.
Let denote the payout random variable per unit currency wagered on an outcome with decimal odds and true underlying objective probability . The expected value is given by:
If the bettor possesses no edge and simply wagers at prices derived from the market's implied probabilities without margin removal, can be approximated as . Substituting this relation into the expected value formula yields:
A5% quoted overround corresponds to expected loss only under proportional probabilities. A5% expected loss instead means five cents per unit. For iid finite-mean returns, the Strong Law of Large Numbers gives almost-sure convergence of the sample mean to expectation; the Weak Law gives convergence in probability. Neither guarantees a finite realized loss. Changing prices, dependence, selection and stopping rules require their own analysis.
3. Deconstructing the 4 Major Devigging Methods
De-vigging converts a complete price vector into probability estimates under assumptions about margin allocation. Quotes alone do not uniquely identify the true probabilities. Comparing a model estimate against another offered price gives model EV; calibration, timing, settlement and executable prices need separate validation.
Because retail bookmakers do not publish their proprietary margin allocation algorithms, quantitative researchers have developed four distinct mathematical paradigms to reverse-engineer fair probabilities: the Multiplicative Model, the Additive Model, the Power (Exponential) Model, and Shin's Insider Trading Model.
Method 1: The Multiplicative (Proportional) Model
The multiplicative method is the most widely utilized devigging technique due to its computational simplicity. It rests upon the foundational hypothesis that the sportsbook applies its profit margin as a constant, proportional multiplier across all outcomes. That is, if a market has an aggregate overround of 5% (S=1.050), the implied probability of each individual selection is assumed to be inflated by exactly 5% relative to its true baseline probability.
Let be the number of mutually exclusive outcomes, and let represent the raw implied probability of outcome . The market overround factor is defined as:
Under the multiplicative model, the fair probability is computed simply by normalizing each implied probability by the total probability mass :
To derive the fair decimal odds , we take the reciprocal of the normalized probability:
Worked Example (English Premier League 1X2):
Consider a high-liquidity football match with published closing lines: Home Win (), Draw (), Away Win ().
- Raw implied probabilities: (47.62%), (29.41%), (28.57%).
- Sum of implied probabilities: (Overround = 5.602%).
- Fair Multiplicative Probabilities:
- Home: (45.09%)
- Draw: (27.85%)
- Away: (27.06%)
- Verification: (100.00%).
Limitation: While algebraically elegant, the multiplicative assumption does not account for the favourite-longshot bias. Real-world sportsbook trading desks often load disproportionate margin onto longshots. On 2,490 Premier League matches (football-data.co.uk) all four methods gave the same accuracy on Pinnacle closing odds (Brier 0.5676). Shin moves probability toward favourites: +0.79 pp for odds below 1.70 and −0.28 pp for odds above 3.50. The choice of method matters most for longshots and for markets with high margins or many outcomes; on liquid EPL 1X2 closing lines it did not improve accuracy.
Method 2: The Additive (Equal Distribution) Model
The additive model operates on the alternative operational assumption that the sportsbook distributes its margin equally across each available outcome in absolute probability space. Rather than scaling probabilities proportionally, the total surplus margin is partitioned evenly among all selections.
The mathematical formulation for fair additive probability is expressed as:
Worked Example (Continuing the Same EPL Match):
With across outcomes, the per-outcome deduction is (1.867 percentage points).
- Home: (45.75%)
- Draw: (27.55%)
- Away: (26.70%)
Critical Analytical Flaw: The additive model exhibits a catastrophic mathematical failure mode when applied to asymmetric markets with longshot contenders. Consider a tennis outright market where an underdog is priced at decimal odds of 60.00 (implied probability or 1.67%). In an 8-competitor market with an overround of 16% (), the equal additive deduction is (2.00%). Subtracting 2.00% from 1.67% yields a negative probability: . Because negative probabilities violate the fundamental axioms of probability, the additive method cannot be universally deployed across multi-runner or longshot betting markets.
Method 3: The Power (Exponential Scaling) Model
Recognizing the mathematical limitations of linear models, quantitative researchers developed the Power Method. This model hypothesizes that sportsbooks distort true probabilities through an exponential compression parameter . By raising each unnormalized implied probability to a power , the model naturally allocates a higher proportion of the margin to lower-probability events, directly reflecting the psychological mechanics of the favorite-longshot bias.
The mathematical condition for the power model requires finding a scalar exponent such that the sum of the transformed probabilities equals exactly 1.000:
Because this equation is non-linear and transcendental, it cannot be solved in closed algebraic form. Instead, quantitative systems deploy the Newton-Raphson numerical algorithm to solve for the unique root . Define the objective function and its first derivative :
Starting with an initial estimate , successive approximations are generated iteratively via:
Convergence to machine precision () typically occurs within 4 to 6 iterations. Once is resolved, each fair probability is computed as . Because and , every probability is compressed downwards while strictly maintaining , entirely eliminating the negative probability hazard inherent in the additive model.
Method 4: Shin's Model (The Insider Trading Adverse Selection Framework)
First introduced in seminal economic literature by Hyun Song Shin in 1991, 1992, and expanded by Joxe (1993), Shin's model provides a structural microstructure framework for margin decomposition based on adverse selection.
Shin's model does not treat the bookmaker's margin as an arbitrary markup. Instead, it models the betting market as an economic game of adverse selection under asymmetric information. The market population is bifurcated into two distinct classes of market participants:
- Uninformed Noise Bettors: Recreational participants who place wagers based on sentiment, media narratives, or public bias, lacking proprietary analytical advantage.
- Informed Traders (Insiders): Market participants possessing private, asymmetric information (such as unpublished team injuries, advanced tactical leaks, or superior predictive models) who know with absolute certainty which outcome will materialize.
The parameter represents the fraction of total market turnover generated by informed traders. To protect itself from catastrophic capital depletion against informed traders, the bookmaker must shade prices downwards. If an informed trader wagers on an outcome, the bookmaker pays out with probability 1.0. Therefore, the bookmaker prices the market such that expected revenue from noise bettors offsets the structural losses incurred against insiders.
Under Shin's formulation, the relationship between raw market implied probability and the true latent probability satisfies the exact quadratic equation:
Solving this system yields the celebrated closed-form Shin fair probability transformation for any given insider parameter :
Where is the sum of raw implied probabilities. The parameter is calibrated dynamically by enforcing the boundary constraint that the sum of all fair probabilities must equal exactly unity:
Using a one-dimensional root-finding algorithm (such as Brent's method or Newton-Raphson), the equilibrium value is resolved in milliseconds. On 2,490 Premier League matches, fitted to Pinnacle closing odds had a median of (between and in 80% of matches); on market-average closing odds the median was . The value rises with the margin, so it is not a direct measure of insider volume.
4. Empirical Comparison: The 2,490 EPL Match Dataset (football-data.co.uk)
To evaluate how these four devigging methodologies diverge in production environments, our quantitative research team analyzed 2,490 Premier League closing lines spanning seven consecutive seasons from August 2019 to January 2026 (source: football-data.co.uk, benchmark dataset: public/papers/epl-closing-lines-2019-2026.csv). Across all 2,490 matches (7,470 1X2 selections), average closing overround was 2.70% on Pinnacle closing lines and 4.16% for the wider market average. In terms of predictive calibration on Pinnacle closing odds, all four devigging models (Multiplicative, Additive, Power, and Shin) deliver virtually indistinguishable predictive accuracy, each registering a Brier score of 0.5676 (differences < 0.0001) and log-loss between 0.9583 and 0.9584. Let us examine a hypothetical scenario illustrating how method choice influences pricing on favourites versus underdogs.
Test Scenario: Extreme Favourite Market (Hypothetical Odds)
Closing Lines: Home Win (), Draw (), Away Win ().
Raw Implied Probabilities: , , . Total Overround: ().
| Methodology | Home Fair P% (1.25) | Draw Fair P% (6.20) | Away Fair P% (12.50) | Home Fair Odds | Away Fair Odds |
|---|---|---|---|---|---|
| Multiplicative | 76.83% | 15.49% | 7.68% | 1.302 | 13.016 |
| Additive | 78.62% | 14.75% | 6.62% | 1.272 | 15.097 |
| Power Model (k=1.064) | 78.86% | 14.34% | 6.80% | 1.268 | 14.707 |
| Shin Model (z=0.021) | 78.17% | 14.92% | 6.91% | 1.279 | 14.472 |
What the example shows: Notice the discrepancy between the Multiplicative and Shin models on the home favorite. The Multiplicative method estimates the favorite's fair probability at 76.83%, whereas Shin's model estimates it at 78.17%—a net shift of +1.34 percentage points. In the 2,490-match sample the average shift for odds below 1.70 was +0.79 pp (across 953 selections), +0.10 percentage points on mid-tier odds (1.70–3.50, 2,848 selections), and −0.28 percentage points on longshots (> 3.50, 3,669 selections). Conversely, on the longshot away team in our scenario, the Multiplicative model assigns 7.68% model probability, while Shin assigns 6.91%.
Relative to Shin, the multiplicative method puts slightly less probability on heavy favourites and slightly more on longshots. Whether that matters depends on the bet: on 2,490 Premier League matches the overall accuracy was the same (Brier 0.5676), but on a single longshot the gap can decide whether the bet looks +EV.
5. Algorithmic Workflow: How Institutional Syndicates Execute Devigging
How do professional quantitative betting syndicates translate these mathematical derivations into systematic trading profits? The execution architecture follows a strict four-stage quantitative pipeline:
- Sharp Line Ingestion: Continuous automated scraping of real-time odds from market-making sportsbooks renowned for market efficiency, high volume limits, and non-restrictive bettor policies (specifically Pinnacle, Circa Sports, and the Betfair Betting Exchange).
- Market Aggregation & Consensus Synthesis: Calculating a volume-weighted composite closing line across sharp venues to eliminate idiosyncratic bookmaker bias.
- Algorithmic Devigging via Shin: Passing the synthesized sharp odds vector into a numerical Shin solver to estimate the fair probability distribution (on liquid 1X2 lines, multiplicative or Power give nearly the same result).
- Soft Market Discrepancy Scanning: Scanning retail, promotional, or regional sportsbooks (soft books) whose lines lag sharp market movements or offer inflated promotional prices. If a soft book offers odds such that , a positive expected value (+EV) dislocation is flagged and bet sizing is computed via the fractional Kelly Criterion.
6. Key Takeaways & Practical Implementation
- Quoted overround describes a complete price vector. Expected loss requires probabilities; under proportional normalization it is m/(1+m). A de-vigged estimate is conditional on a margin-allocation model, not an objective probability revealed by the operator name.
- The Multiplicative Model is a Simplification: While standard across retail calculators, proportional normalization ignores the favourite-longshot bias; on 2,490 Premier League matches it was as accurate as the other methods (Brier 0.5676), but on extreme odds it can disagree with Shin.
- The Additive Model Suffers from Boundary Breakdown: Equal margin deduction can produce catastrophic negative probabilities when applied to multi-runner or deep underdog markets.
- Shin's Model is the Most Theoretically Grounded: Built on the economics of information asymmetry and insider trading, it explains why margin may fall unevenly across outcomes; on liquid EPL 1X2 closing lines it was not more accurate than simpler methods.
- Automate Your Calculations: Explore our free, open-source No-Vig Fair Odds Calculator, which allows you to toggle and compare all four mathematical models across 2-way and 3-way markets in real time.

